Chapter 3 built the incidence matrix of a network,
used it to solve flow problems, and then set one object
aside with a promise: the matrix , the graph
Laplacian, “returns in Chapter 24”. Chapter 7 left a
second debt at the same address. Its exercise Exercise (C1: Counting spanning trees)
computed, for one four-vertex network, that equals the
number of spanning trees, and named the general
statement the matrix-tree theorem, leaving a proof
“which Chapter 24 completes”. This section pays both
debts. It also does something the two earlier chapters
could not: with the spectral theory of Chapters 12 and
17 in hand, we can read the eigenvalues of and find the shape of
the graph in them.
Throughout, a graph means what
Chapter 3 §07 called a network with its orientation
forgotten: a finite set of vertices and a finite
set of edges , each edge joining two
distinct vertices. Two edges may join
the same pair. An orientation chooses,
for each edge , a
tail and a head, and turns the graph back into one of
Chapter 3’s networks with an incidence matrix (Definition 3.7.1).
The
Laplacian of a graph
The matrix has already
appeared three times without being studied: named and
postponed in the closing sentence of Chapter 3 §07’s
flow-network subsection; implicitly in Exercise (C3: Networks in several pieces),
where the kernel of — which, as we
shall see, is the kernel of — turned out to
be spanned by the indicator vectors of the components;
and in Exercise (C1: Counting spanning trees),
where its determinant counted something combinatorial. A
product that keeps coming back deserves a name.
The Laplacian of a graph is the matrix that turns
a labeling of the vertices into the total squared
disagreement across the edges.
Definition
24.11.1 (Graph Laplacian)
Let be a graph
with vertices and edges, and fix any
orientation of ,
with incidence matrix . The
Laplacian of is
In words: the -entry of is the dot product of
row and row of , that is, the sum over
all edges of the product of the two incidence entries.
The definition names an orientation, and the first thing
to check is that the orientation leaves no trace.
Write
for the number of edges meeting the vertex , and for the number of
edges joining to
when , with . Let be the degree matrix
and
the adjacency matrix. Neither mentions
an orientation.
Proposition
24.11.1 (First Properties of the
Laplacian)
Let be a graph
on vertices with
edges and
Laplacian .
Then:
- (a) ; in
particular is
symmetric and does not depend on the
orientation chosen in Definition 24.11.1.
- (b) For every , where
and are the two
ends of the edge .
Consequently .
- (c) , where .
Idea. Everything is one line of
. Part (a) reads
the product
entry by entry, using that a column of has exactly one and one . Part (b) is the
observation that is the
squared length of , and Chapter 3
already identified as the vector of
differences across the edges. Part (c) is (b) applied to
a constant vector, or the fact that each column of sums to zero.
Proof.
(a) By Theorem 0.9.2, . If , then is when meets and otherwise (Definition 3.7.1),
so the sum is . If , then only
for an edge with
one end and the
other , and such
an edge contributes whichever way it is oriented; so the
sum is .
Hence .
Both and are determined by
alone, and is symmetric because
, so
.
(b) As in the
proof of Proposition 3.7.4,
entry of is , which is .
Therefore and expanding the squared length coordinate by
coordinate gives the stated sum, the signs disappearing
because each term is squared. For the standard real
inner product, , which is a sum of squares of real
numbers and hence ; and
is symmetric by (a). So by Definition 13.1.1.
(c) Each column
of has exactly
one and one , so , and .
Part (b) is the whole reason the Laplacian is useful.
A vector is a labeling of the
vertices by numbers, and measures how
badly the labeling disagrees across the edges: it is
zero exactly when the labeling is locally constant, and
large when neighbors receive very different numbers.
Every statement in this section is a consequence of that
one reading.
Example
(A Laplacian computed twice)
Let be the
four-vertex graph of Exercise (C1: Counting spanning trees):
vertices
and edges , , , , . Compute from and from , and check them
against each other.
Solution. The degrees are , , , , and every
pair of vertices is joined by at most one edge, the
missing pair being . Hence Orienting the edges as , , , , gives the
incidence matrix of Exercise (C1: Counting spanning trees),
whose row has squared length
, and
whose rows and
have dot product
.
Continuing entry by entry reproduces the matrix above,
so the two computations agree. Reversing the orientation
of the edge
changes the first two rows of in their first entry
only, from and
to and ; the diagonal entries
are unchanged because they are sums of squares, and the
-entry is
still .
Warning. Take the oriented
incidence matrix, not the unoriented one. If
one replaces the
in Definition 3.7.1 by
, obtaining the
matrix with a
at both ends of
each edge, then , not . That matrix is also symmetric and positive
semidefinite, but it is a different matrix with a
different kernel: for the triangle, is singular while
has
determinant . The
signs are what make Proposition 24.11.1 (b) a
sum of differences, and the sign
convention returns in Lemma 24.11.6, where it is
load-bearing again.
Solution. By Proposition 24.11.1 (b),
each edge contributes the square of the difference of
the labels at its ends. The edges and join equal labels
and contribute ;
the edges ,
and each join a to a and contribute . So , the number
of edges crossing between and . Directly: and .
The
kernel counts the components
Chapter 3’s Exercise (C3: Networks in several pieces)
computed for a network
in several pieces. That was an exercise, so we prove
what we need here, in the form the spectral theory will
use. Recall from Exercise (C3: Networks in several pieces)
the notion we need: two vertices are
linked if some sequence of vertices
joins them with consecutive vertices sharing an edge,
and the equivalence classes of this relation are the
components of . That “linked” is an
equivalence relation (Definition 0.5.2)
takes one line: it is reflexive by the sequence of
length zero, symmetric because a sequence reversed is
again one, and transitive because two sequences may be
concatenated. So the components partition the vertices
(Theorem 0.5.2), which
is what Step 3 below uses.
Theorem
24.11.2 (The Kernel of the Laplacian)
Let be a graph
on vertices with
edges, with
components , and let be the
vector with entry
at the vertices of and elsewhere. Then this list is a basis, and the eigenvalue of has multiplicity
exactly . In
particular is
singular, and exactly when is connected.
Idea. For a positive semidefinite
matrix, lying in the kernel and making the quadratic
form vanish are the same condition, and Proposition 24.11.1 (b)
turns the second one into a statement with no linear
algebra in it at all: the labeling is constant across
every edge. Constant across every edge propagates along
chains of edges, so it means constant on each component,
which is exactly what the indicator vectors
describe.
Proof. Step 1: if and
only if . If , then .
Conversely, if , then by
the display in the proof of Proposition 24.11.1 (b),
so and
.
Step 2: if and only if is constant on each
component. By Proposition 24.11.1 (b),
is a sum
of squares of real numbers, so it vanishes if and only
if every term does, that is, if and only if for every edge
with ends and
. Suppose this
holds and let
lie in the same component. By the definition of linked
there is a sequence with consecutive vertices
joined by an edge, so . Hence is constant on each
component. Conversely, if is constant on each
component, then the two ends of any edge lie in the same
component and carry the same label, so every term
vanishes.
Step 3: the indicators are a basis.
By Steps 1 and 2, if and only if , where is the common
value of on
; so the list
spans . It
is linearly independent: if , then reading the entry at any vertex of
gives , since the
components are disjoint and only the -th vector is non-zero
there. Hence .
Step 4: multiplicity. is symmetric by Proposition 24.11.1 (a),
so by Corollary 12.5.2
it is orthogonally diagonalizable, and the number of
times occurs in
its eigenvalue list is the dimension of its -eigenspace, which is
. That
dimension is , so
is singular. Finally, is connected exactly
when , and
then is the
whole vertex set and .
This is the first of the two theorems that the
Laplacian is for. Notice how little it costs: the entire
combinatorial content sits in Step 2, and the only
property of used
is that its quadratic form is a sum of squares over the
edges.
The
Fiedler value
Theorem 24.11.2 says that
is always an
eigenvalue and that its multiplicity detects whether the
graph falls apart. The natural next question is
quantitative: if the graph is connected, how
connected is it? The eigenvalue just above answers this, and the
reason is Proposition 24.11.1 (b)
again.
Because , all its eigenvalues are (Theorem 13.1.4 (b)),
and it is convenient here to list them
increasingly, against the book’s usual
convention. Write for the eigenvalues of with multiplicity in
increasing order, so that in the decreasing notation
of Chapter 17. By Theorem 24.11.2, .
Definition
24.11.2 (Fiedler value)
Let be a graph
on vertices
with at least one edge. The Fiedler
value, or algebraic
connectivity, of is the second
smallest eigenvalue of its
Laplacian, counted with multiplicity.
For the complete graph , in which every pair
of distinct vertices is joined by one edge, Proposition 24.11.1 (a)
gives , where is the all-ones
matrix. Every row of equals , so and is an eigenvalue of
of multiplicity
by Theorem 3.5.7; and
supplies
the last eigenvalue . Hence has eigenvalues once and with multiplicity , and the Fiedler
value of is
. For a graph in
two or more pieces it is , by Theorem 24.11.2. A single
edge on two vertices has Laplacian and Fiedler value . The degenerate case
is excluded
because there is no second eigenvalue.
Proposition
24.11.3 (Positive Fiedler Value Means
Connected)
Let be a graph
on vertices
with at least one edge. Then if and
only if is
connected.
Proof. The eigenvalues of are , so if and only
if the eigenvalue
occurs at least twice in the list, that is, if and only
if its multiplicity is at least (Theorem 24.11.2). That
happens exactly when has two or more
components, that is, exactly when is not connected.
The number is therefore a
graded version of connectedness, and the grading has a
meaning that can be read off directly.
Proposition
24.11.4 (The Fiedler Value as a Minimum)
Let be a graph
on vertices
with at least one edge. Then and the minimum is attained at an eigenvector
for .
Idea. The quantity being minimized
is the Rayleigh quotient of Chapter 17.
Over all of
its minimum is , attained at , so the constraint
exactly
removes the direction that achieves . What makes this work
is that an orthonormal eigenbasis can be chosen with
as its
first member; after that the computation is the
weighted-average argument of Chapter 17, run once.
Proof. Since is symmetric, Corollary 12.5.2
supplies an orthonormal basis of
with ,
the eigenvalues in the prescribed increasing order;
moreover the basis may be chosen so that .
Indeed, let , of dimension by Theorem 24.11.2, and note
and
. Applying
Gram–Schmidt (Theorem 11.2.2) to
a basis of
beginning with
gives an orthonormal basis of whose first member is
; joining
it to orthonormal bases of the other eigenspaces gives
the required basis, because are the eigenvalues attached to .
Now let with , and write , so that by Theorem 11.2.1 (a).
The constraint says . Hence, by Theorem 11.2.1 (b),
(c), a weighted average of with non-negative weights, not all
zero, being at least the smallest of them. Taking , which
satisfies and is non-zero, gives the value
. So the
set has minimum , attained at
.
A vector achieving the minimum is called a
Fiedler vector. It must have entries of
both signs, since it is orthogonal to , and Proposition 24.11.1 (b)
says it is a labeling that keeps neighbors as close
together as it can while being spread out overall.
Splitting the vertices by the sign of a Fiedler vector
is therefore a reasonable guess at a partition that cuts
few edges.
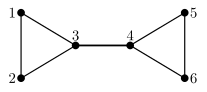
Example
(Two triangles and a bridge)
Let have
vertices and edges , , , , , , : two triangles
joined by a single edge.
Find the Fiedler value and a Fiedler vector, and read
off the partition.
Solution. The degrees are , so
Rather than expand a characteristic
polynomial, guess the shape of the answer from the
symmetry: the graph is carried to itself by the
reflection , , , and
by the swap . Look for an eigenvector
reversed by the reflection and fixed by the swap, that
is, of the form . Rows and of read the other four rows repeating these by
symmetry. Substituting into the second gives , that
is , whose positive root is .
Then The vector satisfies , so by Proposition 24.11.4 its
Rayleigh quotient, which is , is at least ; and , so . To
see that really
is the second smallest, note that and are eigenvectors for
the distinct eigenvalues and , and check that the
remaining four eigenvalues are larger: the vectors , and are
eigenvectors for the eigenvalue , as one verifies row by
row, and they are visibly independent, so together with
and they account for five
of the six. For the third of them, for instance, row
of gives and row gives .
The trace of is
,
so the sixth eigenvalue is , also larger than . Hence is a Fiedler vector, and the signs of its
entries split the vertices as : exactly the two triangles, cut along the
bridge.
Compare the Fiedler value of this
graph with the value for . Small means “nearly
disconnected”, and the bridge is what makes it small.
One general fact in that direction is immediate from
Chapter 17.
Proposition
24.11.5 (Adding an Edge Raises No Eigenvalue)
Optional: nothing later
depends on this.
Let be a graph
on vertices with
at least one edge, and let be with one extra edge
joining .
Then with , and In particular the Fiedler value does not
decrease when an edge is added.
Proof. The extra edge adds to and to and to and , so by Proposition 24.11.1 (a),
has
entries at and , at and , and elsewhere; that matrix
is . Now
is
symmetric, and for every , so and
in the Loewner order (Definition 13.5.1). By
Corollary 17.2.4,
for every , and rewriting the
decreasing index as the increasing index gives the claim.
Counting
spanning trees
Now the second theorem, and the one Chapter 7
promised. Two more words are needed, and both are about
the graph alone.
A cycle is a set of edges with
that can be
listed together with distinct vertices
so that, setting , the edge joins to for each . Two edges joining the
same pair of vertices form a cycle with . A spanning
tree of
is a set of edges
such that the graph with all vertices and only the
edges of is
connected and contains no cycle. In Exercise (C1: Counting spanning trees)
the phrase was “a set of edges that connects all
four vertices”, and the proposition below reconciles the
two descriptions.
The bridge from graphs to determinants is the
following lemma. It is where such proofs usually go
wrong, so read the third part carefully: it is a
statement about submatrices of with one row deleted,
not about arbitrary square submatrices, and the “exactly
when” is an equivalence in both directions.
Lemma
24.11.6 (Unimodularity of Incidence
Minors)
Let be the incidence matrix of an oriented
graph with vertices and edges. Write
for
the column of
belonging to the edge .
- (a) Every square
submatrix of has
determinant ,
or .
- (b) For a set of edges, the list
is
linearly independent if and only if contains no cycle.
- (c) Fix a vertex
and put .
For a set of
exactly edges, is a spanning tree of
if and only if it
contains no cycle, and
Idea. ① For (a), induct on the size
of the square submatrix and look at its columns. A
column of
restricted to a subset of the rows keeps at most the one
and the one . If some column of the
submatrix is zero, the determinant is ; if some column has a
single non-zero entry, expand along it and the size
drops; and if every column has both,
then the rows of the submatrix add up to zero, so they
are dependent. ② For (b), a cycle gives an explicit
dependence — walk around it and the telescoping sum
collapses. Conversely a dependence, restricted to the
edges with non-zero coefficient, forces every vertex to
meet either none or at least two of them, and a finite
graph with that property contains a cycle. ③ Part (c)
combines the two, once one knows that deleting the row
costs no rank,
which it does not, because the rows of already sum to
zero.
Proof. (a) We
induct on , the
common number of rows and columns of the square
submatrix . For , is a single entry of
, which is , or by Definition 3.7.1.
Let and
assume the claim for . Each column of has exactly one and one , so each column of
has at most one
and at most one
and no other
non-zero entries. Three cases.
Case 1: some column of is zero. Then
by Theorem 7.2.1.
Case 2: some column of has exactly one
non-zero entry , in row say. Expanding
along that column (Theorem 7.6.1) gives
, where is with that row and
column deleted. But is again a square
submatrix of , of
size , so by the induction hypothesis, and hence so
is .
Case 3: every column of has both a and a . Then every
column sums to ,
so the sum of all
rows of is the
zero row; the rows are linearly dependent, and by Theorem 7.2.1 and Theorem 7.4.5.
These three cases are exhaustive, which completes the
induction.
(b) We prove the
contrapositive: suppose with some , and let , a non-empty subset of . Fix a vertex . Entry of the sum is , and exactly
for the edges of meeting , and otherwise. If exactly
one edge met , that entry would be
,
contradicting the sum being . So every
vertex meets either no edge of or at least
two.
Now build a walk. Pick any , with ends
and . Having reached along , the vertex meets at least two
edges of , so
we may choose with meeting , and let be its other end.
Since there are only vertices, some vertex
repeats; let be
the smallest index with , and let be the index
with .
Then are distinct, by the minimality of
, and join
them in a closed chain. Put . First, : would mean that
joins to itself, and an
edge joins two distinct vertices.
Second, the edges
are distinct: for that is the construction, ; and
for the
pairs for are pairwise different pairs of the
distinct vertices , so the edges joining them
differ. So is a cycle, and it lies in .
Again by contraposition. Let be a cycle with vertices and
as in the
definition. For each set if
is oriented
from to
, and
otherwise. By Definition 3.7.1
the column of an edge oriented from to is , so in either
case . Summing telescopes:
a dependence with all coefficients , so the list is
dependent.
(c) Write for the full columns and
for the same columns with row deleted. Every column
of sums to , so row of is minus the sum of
the other rows; deleting it therefore does not change
the row space, and by Theorem 3.5.5 Hence if and only if (Theorem 3.4.4 and
Theorem 7.5.2), that
is, if and only if the columns are
linearly independent, which by (b) holds if and only if
contains no
cycle. When it does not vanish, by
(a).
It remains to check the equivalence in the statement:
for a set of
edges, “no
cycle” and “spanning tree” agree. A spanning tree
contains no cycle by definition. Conversely, suppose
has edges and no cycle;
we must show that the graph with all vertices and the edges
of is connected.
By (b) the columns of are independent, so
and
. Each column of lies in , which has dimension as computed in the
proof of Corollary 3.7.5, so
by
Theorem 1.6.8.
Suppose were
disconnected, and let be the vertex set of
one of its components, so .
Every edge of has
both ends in or
both ends outside , so for every
, and hence
for
every . But choosing and gives with , a
contradiction. So
is connected, and
is a spanning tree.
One consequence of the last paragraph of the proof is
worth recording separately, since it is what makes the
sum in the theorem below a sum over spanning trees
rather than over sets of every size.
Proposition
24.11.7 (A Spanning Tree Has Edges)
Let be a graph
on
vertices. Every spanning tree of has exactly edges. Conversely,
if a set of
exactly edges
is such that the graph on all vertices with edge set
is connected,
then is a
spanning tree.
Proof. Let be a spanning tree and
let be the graph
on all vertices
with edge set .
Then is
connected, so (for ) and Proposition 3.7.4
applied to gives
,
where is the
incidence matrix of with some orientation,
that is, the columns of indexed by . Also contains no cycle, so
those columns are linearly independent by Lemma 24.11.6 (b), and
therefore .
Conversely, let have exactly edges and let be the graph on all
vertices with
edge set , assumed
connected. By Proposition 3.7.4
applied to , , where
is the
incidence matrix of , that is, the columns
of indexed by
; it has columns, so Theorem 3.5.7 gives
; since by Theorem 0.9.3, the
columns are linearly independent. By Lemma 24.11.6 (b), contains no cycle, and
is connected, so
is a spanning
tree. In particular the sets counted here are exactly
the “sets of
edges that connect all four vertices” of Exercise (C1: Counting spanning trees).
Theorem
24.11.8 (Matrix-Tree Theorem)
Let be a graph
on vertices
with edges
and Laplacian .
Fix a vertex , and
let be with the row and the
column of
deleted, where . Then In particular the answer does not depend on
which vertex is
deleted, and exactly when is disconnected.
Idea. The determinant of is the determinant
of a Gram matrix, because for
the reduced incidence matrix . Corollary 7.7.3
writes such a determinant as a sum of squares of
minors, one for each set of edges. Lemma 24.11.6 says that
each of those squares is for a spanning tree and
for anything
else. So the sum counts spanning trees, one apiece.
Every step has already been proved; the theorem is the
three of them placed in a row.
Proof. Fix an orientation of , with incidence matrix
, and put , the matrix with the row of deleted.
Step 1: . By Theorem 0.9.2, the
-entry of
is row
of dotted with row of . Deleting the row and
the column of
from
therefore leaves exactly the dot products of the rows
indexed by , which
is .
Step 2: Cauchy–Binet. Applying Corollary 7.7.3 to
, one term for each set of exactly edges. The submatrix
keeps all rows of and the columns
, so it is the
submatrix of on
rows and columns
, namely .
Step 3: identify the terms. By Lemma 24.11.6 (c), when
is a spanning
tree and
otherwise, so each term of the sum is for a spanning tree and
otherwise. By Proposition 24.11.7 every
spanning tree has exactly edges, so every
spanning tree occurs as one of the sets , and it occurs once.
Hence the sum is the number of spanning trees.
The left-hand side of Step 2 was computed from a
particular , and
the right-hand side does not mention , so the value is the
same for every choice. Finally, a disconnected graph has
no spanning tree, since a spanning tree is connected on
all vertices, so
the sum is empty and . A connected
graph has at least one: by Proposition 3.7.4,
, and
deleting the row of does not change the row
space, since every column of sums to , so by Theorem 3.5.5. As
has rows, Theorem 7.7.1 (a)
gives a non-zero minor of , which uses all its
rows and some set
of columns;
that minor is , so is a spanning tree by
Lemma 24.11.6 (c). Hence
exactly when is
disconnected.
Solution. Deleting the row and
column of vertex
from the Laplacian computed in Example (A Laplacian computed twice)
leaves the matrix whose determinant Exercise (C1: Counting spanning trees)
(a) expands along its first row: .
Now count directly. A spanning tree has edges by Proposition 24.11.7, and
there are sets of three edges. By Lemma 24.11.6 (c) such a
set fails to be a spanning tree exactly when it contains
a cycle, and the only cycles with three or fewer edges
are the triangles on vertices and on
vertices , in
the edge numbering of Example (A Laplacian computed twice).
So of
the sets are spanning trees, matching .
As a check on one term of the sum in the proof, the
tree gives, on rows , lower triangular with determinant (Theorem 7.4.6). The
matching computation for a non-tree, whose minor is
, is Exercise (C1: Counting spanning trees)
(d).
Warning. Delete one row and
the matching column, and no more. The Laplacian
itself is always singular by Theorem 24.11.2, so says nothing.
Deleting two vertices does not count
anything either: for the four-cycle with edges , striking out the rows and columns of
and leaves , of
determinant ,
while the graph has spanning trees. And the
proof needs the deleted row and the deleted column to
belong to the same vertex, since Step 1
produces a Gram matrix only then;
that is a constraint on this route, and nothing above
claims that a mismatched pair of deletions counts
nothing. Note also that the theorem counts sets
of edges, so parallel edges count as different
trees: two vertices joined by three parallel edges have
, and three
spanning trees, one per edge.
Two theorems, both proved from the single identity
and the single factorization . The first
reads the graph’s components off the spectrum of ; the second reads the
number of its spanning trees off one determinant,
replacing a search over all edge sets
by one
elimination (Proposition 24.2.3 (a)).
Both are statements about a graph that no purely
combinatorial argument delivers as cheaply.
Exercises
A. Check your
understanding
Exercise
(A1)
- (a) Define the
Laplacian of a graph, and say why it does not depend on
the orientation used to define it.
- (b) Write down the
formula for as a sum over
edges, and deduce that .
- (c) State the
matrix-tree theorem, including all its hypotheses.
- (d) True or false: a
graph on vertices
is connected if and only if . Justify
your answer.
- (e) True or false:
if has
eigenvalue with
multiplicity ,
then . Justify your answer.
Solution.
(a) With the incidence matrix
of any orientation, (Definition 24.11.1). By Proposition 24.11.1 (a),
, and
the degree matrix and the adjacency matrix are
determined by the graph alone.
(b) , where are the ends of
(Proposition 24.11.1 (b)).
This is a sum of squares of real numbers, hence , and is symmetric, so by Definition 13.1.1.
(c) For a graph
on vertices
with at least one edge, and any vertex , the matrix obtained from by deleting the row
and the column of
satisfies the number of spanning trees (Theorem 24.11.8). Multiple
edges are allowed; loops are not, since edges join
distinct vertices.
(d) True. By Theorem 24.11.2, , the
number of components, so Theorem 3.5.7 gives
;
and is
connectedness.
(e) True.
Multiplicity
means by Theorem 24.11.2, so the
graph is connected and has at least one spanning tree,
and
by Theorem 24.11.8.
B. Practice
Exercise
(B1: The four-cycle)
Let be the
graph on vertices with edges .
- (a) Write down and explain why it is
a circulant in the sense of Definition 12.9.1.
- (b) Find all
eigenvalues of ,
the Fiedler value, and a Fiedler vector.
- (c) Compute and list the
spanning trees.
Solution.
(a) Every vertex
has degree , and
the vertices
are joined exactly when . So, numbering rows and
columns
as in Chapter 12 §09, the -entry depends only
on modulo
, which is Definition 12.9.1;
the first row is and
(b) By Theorem 12.9.4 the
eigenvalues are for
, with
. These were computed in Exercise (B1: Eigenvalues of small circulants)
(c): ,
,
,
. In
increasing order the eigenvalues are , so the
Fiedler value is . A real eigenvector for is twice the real part
of the Fourier vector , namely ; it is
orthogonal to ,
and , confirming the eigenvalue. So is a Fiedler
vector, splitting the cycle as with
and undecided.
(c) Deleting the
row and column of vertex , Directly: a spanning tree has edges, and the only
-edge subsets that
are not spanning trees would have to contain a cycle;
the only cycle is all four edges, so every one of the
three-edge subsets is a spanning tree. Both counts give
.
Exercise
(B2: Counting trees in a bowtie)
Let have
vertices and edges : two triangles
sharing the vertex .
- (a) Write down and compute with .
- (b) Count the
spanning trees directly, and check that the two answers
agree.
- (c) Verify that
is an eigenvector of , and say what its
eigenvalue tells you.
Solution.
(a) The degrees
are ,
so Expanding along the first
row: .
The first determinant is , and the second is . So .
(b) Removing the
vertex separates
the graph into the two triangles, and a set of edges is
a spanning tree exactly when it meets each triangle in a
spanning tree of that triangle: the two triangles share
only the vertex ,
so no cycle can use edges from both, and connectedness
of the whole is connectedness of each half through . Each triangle has
spanning trees,
namely its pairs
of edges. Hence there are spanning trees, agreeing with
(a).
(c) has entries , , ,
,
, so
and the
eigenvalue is .
Since ,
Proposition 24.11.4 gives
. The Fiedler value is therefore at most , much smaller than the
value for the
complete graph ,
computed after Definition 24.11.2, and
the sign pattern of proposes the partition
with the shared vertex sitting on the fence:
the graph is nearly two pieces.
Exercise
(B3: Which minors are ?)
Let be the
graph on vertices with edges , , , (so and are parallel). Orient
every edge from the smaller vertex to the larger, let
and .
- (a) Write down and .
- (b) Compute for all six
sets of two
edges, and say in each case whether is a spanning
tree.
- (c) Hence find the
number of spanning trees, and check it against .
Solution.
(a) Column has at the tail and at the head:
(b) Taking the
two columns in increasing order each time, Five of the six are and those five sets
are spanning trees: each is a pair of edges covering all
three vertices with no cycle. The exception is , a cycle of
length formed by
the parallel pair, which misses the vertex entirely; its minor is
, as Lemma 24.11.6 (c)
predicts.
(c) So there are
spanning trees.
The degrees are , , , and , , so The two answers agree.
C. Going deeper
Exercise
(C1: Cayley’s formula)
Let be the
complete graph on vertices, in which every pair of distinct
vertices is joined by exactly one edge, and let be the
all-ones matrix.
- (a) Show that the
Laplacian of is
, and
that for every choice of deleted
vertex.
- (b) Prove that .
- (c) Deduce
Cayley’s formula: has exactly spanning trees.
Check it for against a direct count.
Hint for (b): the eigenvalues of are visible from its
rank and its row sums.
Solution.
(a) Every vertex
of has degree
and for , so by Proposition 24.11.1 (a),
Deleting the row and column of any one vertex
from
leaves , since the pattern of entries is the
same at every vertex.
(b) Put . The matrix is symmetric with
every row equal to , so and by
Theorem 3.5.7;
hence is an
eigenvalue of multiplicity at least . Also , so is an eigenvalue. That
accounts for
eigenvalues, so the eigenvalue list of is . Therefore
has
eigenvalues once and with multiplicity , and since is symmetric it is
diagonalizable (Corollary 12.5.2),
so
(c) By Theorem 24.11.8 and parts
(a), (b), the number of spanning trees of is . For
: , and indeed the
single edge is the only spanning tree. For : , and the
triangle’s spanning trees are its three pairs of edges.
For : ; directly, has sets of
three edges, of which the triangles are the only
ones containing a cycle, leaving .
Exercise
(C2: Weighted graphs)
Give each edge
of a graph on
vertices a
weight ,
let , and define the weighted
Laplacian , with the incidence matrix
of any orientation.
- (a) Prove that , and deduce that with
the same kernel as .
- (b) Prove the
weighted matrix-tree theorem: for any vertex , the sum running over all spanning trees of .
- (c) Check (b) on the
graph of Example (A Laplacian computed twice)
by comparing the coefficient of on both sides,
and confirm that setting every recovers Theorem 24.11.8.
Hint for (b): .
Solution.
(a) Let , so and
is
symmetric. Put . Then and, as
in Proposition 24.11.1 (b),
since entry of
is times
entry of . The matrix is
symmetric because ,
and the sum is , so . As in Steps 1 and 2 of the proof of
Theorem 24.11.2, if
and only if this sum vanishes; every is
strictly positive, so the sum vanishes
exactly when every difference does,
which is the same condition as for . Hence the kernels
agree.
(b) With as above
and , the argument of Step 1 of Theorem 24.11.8 gives
with . By Corollary 7.7.3,
Multiplying on the right by the
diagonal matrix scales column
by , so and, by Theorem 7.5.4 and Theorem 7.4.6, By Lemma 24.11.6 (c) the
first factor is
when is a
spanning tree and
otherwise, and by Proposition 24.11.7 every
spanning tree has edges and so occurs
among the sets ,
once. This gives the formula.
(c) For that
graph, with
and the edge numbering , , , , , The weight occurs only in the
-entry, so in
the Leibniz expansion (Definition 7.4.1)
only the two permutations fixing can produce a term
containing : the
identity, contributing ,
and the transposition of and , contributing ,
every term of which carries a factor . So the coefficient
of comes
from the diagonal product alone, and there it is . On the right, a
spanning tree
contributes the single monomial , and
is recovered from
that monomial, so the coefficient of is if is a
spanning tree and
otherwise; it is one, as Example (The four-vertex graph, counted both ways)
records. Setting every gives , hence , and the right-hand side becomes the number
of spanning trees: Theorem 24.11.8.