Chapter 5 attached to every linear map a dual
map running backwards between the dual spaces
(Definition 5.4.1). An
inner product puts a copy of the dual space back inside
the space itself, by the Riesz correspondence of Theorem 11.5.1.
Composing the two turns the backward map on functionals
into a backward map on vectors, . That map is the
adjoint , and it is the
single most useful construction in this chapter. This
section builds it, computes its matrix, uses it to split
both and into orthogonal pieces,
and names the two classes of operators it singles
out.
Throughout, is
or , every inner product
is linear in the first slot and conjugate-linear in the
second, and every inner product space is
finite-dimensional over unless we say
otherwise.
Paying to
cross the inner product
Here is the situation the adjoint answers. We have a
linear map and an
inner product, and an expression like in which
sits in the first
slot. Very often the argument needs out of the way: we know
something about ,
or about the second slot, and the is in the wrong place.
Can we move it across?
For matrices the answer is already on the table. Lemma 11.4.1,
proved in Section 4, says that for ,
and
, with the conjugate
transpose of Definition 11.1.2.
The one-line reason is worth repeating, because it is
the model for the whole section: writing for the row vector
, the
standard inner product is the matrix product , so . So a
matrix does cross the inner product, and the price is a
conjugate transpose. Over the price is a
transpose; over
a transpose and a conjugation.
To move a map from the first slot to the second
slot, you pay with a new map going the other
way.
That statement is about matrices and the standard
inner product. The next theorem says the same map exists
for every linear map between finite-dimensional inner
product spaces, with no coordinates at all. Riesz does
the work: the expression , read as
a function of
with frozen, is
a linear functional on , and Theorem 11.5.1 says
that every such functional is pairing against one fixed
vector.
Theorem
11.6.1 (Existence and Uniqueness of the
Adjoint)
Let and be finite-dimensional
inner product spaces over , and let . Then
there is exactly one map such
that and this is linear.
Idea. Freeze . Then is a functional on , so Riesz hands us one
vector that represents it; call it . That is the
whole of existence, and it also gives uniqueness, since
the Riesz vector is unique. Linearity is not part of the
construction and has to be checked, and the way to check
an identity between vectors is the signature move of
this chapter: show the difference pairs to zero with
everything, then pair it with itself.
Proof. Existence.
Fix and
define by . It is linear: for and
, using the linearity of and linearity in the
first slot (Definition 11.1.1).
Since is
finite-dimensional, Theorem 11.5.1
gives a unique with for all . Define . By
construction for all , which is the required
identity.
Uniqueness. Suppose also
satisfies for all . Fix . Then for every , by conjugate-additivity in the second slot.
Taking gives , so by positive definiteness (Definition 11.1.1).
As was
arbitrary, .
Linearity. Let and
. For every
, where the second and the last equalities use
conjugate-linearity in the second slot. Hence for every , and pairing the
right-hand vector with itself makes it . So is linear. This
proves the theorem.
Notice where the two conjugations went. The scalar
came out of the
second slot as and went back in
as ; the two
conjugations cancel, which is exactly why is linear and not
conjugate-linear. Notice also that only had to be
finite-dimensional: the proof never uses a basis of
. We keep both
spaces finite-dimensional because the rest of the
section does need it.
The
adjoint
The theorem produced an object attached to and to the two inner
products, and it is unique, so it deserves a name and a
notation.
The adjoint of is the map you must
apply on the other side of the inner product to leave
the value unchanged.
Definition
11.6.1 (Adjoint)
Let and be finite-dimensional
inner product spaces over and let . The
adjoint of is the unique linear
map satisfying
In words, clause by clause:
- goes
backwards: its domain is the codomain
of . If then
, like the dual map and unlike anything else
we have attached to .
- The defining equation is an identity in
two variables, and it must hold for
all and
all . By linearity in the
first slot and conjugate-linearity in the second, it is
enough to check it when and range over bases of
and of , and that is usually
how gets
computed.
- The left inner product lives in , the right one in . They are different
inner products; only the notation hides it.
- The definition mentions no basis, but it does
mention the two inner products. Change an inner product
and
changes.
Example
(Four Adjoints)
Compute the adjoint in each case. In (a) and (b) the
spaces carry the standard inner product; in (c) and (d),
and are arbitrary
finite-dimensional inner product spaces.
- (a) for .
- (b) The forward
shift , .
- (c) and the zero map
.
- (d) The orthogonal
projection onto a subspace .
Solution.
(a) By Lemma 11.4.1, for all , which is the
defining identity of the adjoint; so
for every matrix, by uniqueness in Theorem 11.6.1.
Here so .
(b) Directly from
the definition, for , The two agree for all and . So is the
backward shift . The forward shift pushes coordinates up;
its adjoint pushes them down and drops the one that
falls off the end.
(c) , so . For
the zero map, for every , so , the zero map
. These are
the degenerate cases, and they say the adjoint fixes
what should be fixed.
(d) By Theorem 11.3.3 (b),
for all . Since is an operator on
, this is exactly
the defining identity for its own adjoint, so by
uniqueness in Theorem 11.6.1.
Part (d) is the first place where uniqueness earns
its keep: we did not construct , we recognized an
identity we already had and read the answer off it. That
move recurs throughout the section.
Example
(Differentiation on a Polynomial Space)
On define for
and . (This is the standard inner product of
transported
by the coordinate map, so it is an inner product, and
is an orthonormal basis.) Find the adjoint of , .
Solution. For as above, , so
We need with equal to the line above for
all . Comparing coefficients of gives , , . Hence So
raises degrees where lowers them. It is not
an antiderivative: the coefficient and the discarded both say so.
Here is a non-example by minimal change, and it
explains the conjugate. On , keep the standard
inner product but try the plain transpose: is ? Take , which is symmetric, so
, and
take . Then , while .
The two sides differ. Everything about the transpose
still works — it is linear and it reverses products —
but it fails the one clause that matters, the defining
identity, and it fails it by a conjugation. Over the conjugation is
invisible and the transpose is correct.
Why this definition. We could have
asked instead for a map with . Conjugating Definition 11.6.1
shows that as well, so nothing new appears; the
convention above is the one that reads left to right.
The notation
matches the matrix notation of Example (Four Adjoints)
(a), which is the point of the star. The word
adjoint is unrelated to the adjugate
of Definition 7.6.2; the
collision of names is historical and the two objects
have nothing to do with each other.
Warning. The adjoint
depends on the inner product, not on alone. On
take .
With the standard inner product, . With the weighted inner product , which is also an inner
product, we need to equal for all , which forces and .
So the adjoint is now , a different map.
Writing
without saying which inner product is meant is as
incomplete as writing a matrix of without saying which
basis.
Quick check. Let with
. Can ?
Solution. No. If then for all . Taking gives , so
for every
, that is . This is the “pair
it with itself” move again.
Finally, the finite-dimensional hypothesis is not
decoration.
Example
(A Map With No Adjoint)
On ,
all polynomials, define , a finite sum since the coefficients
vanish eventually. Show that , , has no adjoint.
Solution. is linear, being
evaluation at
followed by multiplication by the constant polynomial
. Suppose existed. Apply the
defining identity with and with , the constant polynomial: since , But is
the coefficient of in , so every
coefficient of the polynomial equals . No polynomial has
infinitely many non-zero coefficients, a contradiction.
So does not
exist.
What failed is Riesz: the functional on is not pairing
against any vector, precisely as in the
infinite-dimensional discussion of Section 5.
Arithmetic
of the adjoint
Starring behaves like transposing: it is additive,
conjugate-homogeneous, order-reversing on products, and
an involution.
Theorem
11.6.2 (Properties of the Adjoint)
Let be
finite-dimensional inner product spaces over .
- (a) For , .
- (b) For and , .
- (c) For and , .
- (d) for every
,
and .
- (e) If is
invertible, then is invertible and
.
Idea. Each claim says that two maps
agree. By
the uniqueness in Theorem 11.6.1, it
is enough to check that the proposed right-hand side
satisfies the defining identity of the left-hand side.
So every proof is one chain of inner products, and
nothing is ever solved for. Part (e) needs no chain at
all: star the two equations and and use
(c) and (d).
Proof. Throughout, and denote arbitrary
vectors of the relevant spaces, and each verification
ends by invoking uniqueness in Theorem 11.6.1.
(a) , the last step by additivity in the
second slot.
(b) , where the last
equality puts into the second
slot, which conjugates it back to .
(c) For and , using the
defining identity for and then for ,
(d) The map has
its own adjoint , determined by . Conjugating the defining
identity of
and using the conjugate symmetry of the inner product
(Definition 11.1.1),
So
satisfies the identity that defines , and . That is Example (Four Adjoints)
(c).
(e) Suppose is invertible, with
. Applying (c) and (d) to and to
,
Both composites are identities, so is invertible with
inverse (Definition 2.5.1).
This proves the theorem.
Parts (a) and (b) say that is
conjugate-linear, not linear: over
it is the same
half-twist that the Riesz map carries in Corollary 11.5.2,
and for the same reason. Part (c) is the order reversal
familiar from transposes and from dual maps (Theorem 5.4.1 (b)). Part
(d) says that starring is an involution, so no new maps
appear by starring twice.
The matrix
of the adjoint
Now fix bases and compute. The conclusion is the one
the opening computation suggests, provided the
bases are orthonormal; the hypothesis is where
all the content sits.
Theorem
11.6.3 (The Matrix of the Adjoint Is the
Conjugate Transpose)
Let and be finite-dimensional
inner product spaces over , let
be an orthonormal basis of and
an orthonormal basis of , and let . Then
Idea. In an orthonormal basis a
coordinate is an inner product (Theorem 11.2.1), so
every matrix entry is an inner product, and the defining
identity of
says precisely how those inner products are related.
Write both entries out and compare.
Proof. Write
and , of sizes and . By Definition 4.1.1,
the -th column of
holds the
coordinates of in , and by Theorem 11.2.1
those coordinates are inner products: By conjugate symmetry and Definition 11.6.1,
So is
the matrix whose entry is , which is
. This proves
the theorem.
Both hypotheses were used: orthonormality of to read off , orthonormality of
to read off
. Drop either
one and the conclusion fails.
Warning. The rule is false in a
basis that is not orthonormal. The next example
exhibits a two-dimensional counterexample with integer
entries. The correct general statement involves the Gram
matrix and is recorded in the remark after it.
Example
(The Transpose Rule Breaks)
Work in
with the standard inner product and let .
Let with and . Compute and
,
and compare the second with the transpose of the
first.
Solution. First, is a basis (two
independent vectors in ) but it is not
orthonormal: and .
By Example (Four Adjoints)
(a) with , the adjoint is .
The matrix of . and , so
The matrix of . and
.
Solving gives and , so both columns are :
The two displayed matrices are different: the
transpose rule fails. A quick sanity check that nothing
else went wrong: the traces are and , and both matrices have
rank , as they
must, since .
The
adjoint and the dual map
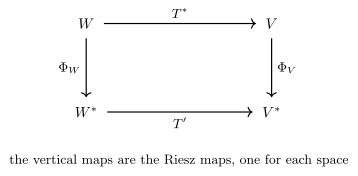
Two backward maps are now attached to : the dual map of Definition 5.4.1, which
needs no inner product and sends a functional to , and the
adjoint , which does need one. The Riesz map converts
one into the other. This subsection is a connection, not
a tool: nothing later in the book is proved with it, so
a reader who has not met Chapter 5 can go straight to
the next subsection and lose nothing.
Recall from Corollary 11.5.2
the Riesz map, the conjugate-linear bijection and likewise for . The following square
commutes: the two backward maps run horizontally, the
two Riesz maps vertically, and the two routes from to agree.
Theorem
11.6.4 (The Adjoint Is the Dual Map Read
Through Riesz) Optional:
nothing later depends on this.
Let be
finite-dimensional inner product spaces over and . Then
Proof. Both sides send to a functional
on , so evaluate
them at an arbitrary . By Definition 5.4.1 and the
definition of , while by Definition 11.6.1
and the definition of , The two agree for all and all , so the two maps are
equal.
Read backwards, the identity says : transport a vector of
into , pull it back with
the dual map, transport it back into . So the adjoint carries
no information that does not already
carry; what it carries is the inner product used to
transport. The matrix statements match too. In dual
bases the matrix of is the transpose
of the matrix of
(Theorem 5.4.2); in
orthonormal bases the matrix of is the conjugate
transpose (Theorem 11.6.3).
The extra conjugation is the price of being
conjugate-linear, and over it disappears, which
is why the two constructions are so easily confused
there.
The four
fundamental subspaces
Chapter 3 attached four subspaces to a matrix: and (Definition 3.5.1,
Definition 3.5.3)
together with (Definition 3.5.2)
and the null space of the transpose. Chapter 5 related
two of them, with Theorem 5.6.5: the row
space of
is the annihilator of , so every linear
equation satisfied by the solution set is a combination
of the given ones. That statement lived in the dual
space, and Definition 5.2.1 carried a
warning with it: over a general field the annihilator
has no right to be pictured as a perpendicular. With an
inner product, it does. The four subspaces become two
orthogonal splittings, one in each of the two
spaces.
Theorem
11.6.5 (The Four Fundamental Subspaces)
Let be
finite-dimensional inner product spaces over and let . Then
- (a) ;
- (b) ;
- (c) ;
- (d) .
Idea. Only (a) needs an argument,
and it is one chain of equivalences: says a
vector is zero, so pair it with everything, and the
defining identity turns “everything” into “everything in
the image of ”.
Then (b) is (a) applied to , using , and
complemented with .
Parts (c) and (d) are then just the orthogonal
decomposition theorem.
Proof.
(a) Let . Then The second equivalence is non-degeneracy:
forwards it is immediate, and backwards we take and get
. The third is Definition 11.6.1.
The fourth is Definition 11.3.1
together with conjugate symmetry, since if
and only if , and the vectors are exactly the
elements of .
Every step is reversible, so both inclusions come at
once.
(b) Apply (a) to
in place of .
Since by
Theorem 11.6.2 (d),
this reads . Taking orthogonal complements
and using
for a subspace of
a finite-dimensional space (Theorem 11.3.2
(b)),
(c) is a subspace of
(Theorem 2.2.1), so
by Theorem 11.3.2 (a),
and by (b).
(d) Likewise
by Theorem 11.3.2 (a),
and by (a). This proves the theorem.
For a matrix with the standard inner products,
, so the theorem reads with and . Over the columns of are the rows of
turned into
vectors, so the second identity is the promised
statement that the row space and the null space
are orthogonal complements of each other in
. This is Theorem 5.6.5 with the
annihilator replaced by the orthogonal complement,
exactly as Corollary 11.5.2
licenses; and taking dimensions returns Rank–Nullity for
matrices (Theorem 3.5.7) one
more time. Section 4 proved the identity directly, because the minimum-norm
solution needed it; the theorem above is that
computation done once for all four subspaces and for
maps rather than matrices.
Example
(All Four Subspaces of a 3 × 3 Matrix)
For over , find bases of the
four subspaces and verify the two orthogonality
statements.
Solution. Row three is the sum of
rows one and two, and rows one and two are independent,
so and
has the
basis (written as vectors).
Null space. reduces to and , so , of dimension , as Theorem 3.5.7
requires.
Orthogonality in the domain. and . So ,
and since
the two are complementary: .
Column space. Columns one and two are
independent and column three is column two minus column
one, so .
Null space of the transpose. reads , ,
,
giving .
Orthogonality in the codomain. and , and , so .
Corollary
11.6.6 (Rank of the Adjoint)
Let be
finite-dimensional inner product spaces over and . Then
- (a) ;
- (b) ,
and consequently .
Proof.
(a) By Theorem 11.6.5 (b)
and a dimension count, the middle equality by Theorem 11.3.2 (c)
and the last by the Rank–Nullity Theorem (Theorem 2.3.1).
(b) If then .
Suppose
. Then
so . Hence the kernels agree. Both and are defined on , so Rank–Nullity gives
.
Part (a) is a fourth proof that row rank equals
column rank, after the three of Chapters 3, 4 and 5: for
a real matrix it says . Part (b) is the engine of the
normal equations: it is why is invertible
exactly when has
independent columns, which is the hypothesis in Corollary 11.4.4.
Quick check. Let with
, and . What are
and
?
Solution. by Corollary 11.6.6
(a), so ; and with , so . The same number comes from
Theorem 11.6.5 (a):
.
Self-adjoint and normal operators
For an operator , the adjoint lives in the same space
, so we may
compare with
. Two
comparisons matter, and everything in the next chapter
rests on them.
A self-adjoint operator is one that costs nothing
to move across the inner product.
Definition
11.6.2 (Self-adjoint Operator)
An operator on a finite-dimensional inner product
space is self-adjoint if , that is, if
The matrix counterpart is the
Hermitian matrix of Definition 11.1.2,
; over
this says , and the
matrix is symmetric.
In words:
is not a new map but over again, so must be an
operator, with the same space and the
same inner product on both sides; and the displayed
identity is the defining identity of Definition 11.6.1
with
rewritten as ,
still required for all and
all .
By Theorem 11.6.3, an
operator on a finite-dimensional inner product space is
self-adjoint exactly when its matrix in one
(equivalently every) orthonormal basis is Hermitian.
Three examples to keep in mind: the orthogonal
projection onto
any subspace, self-adjoint by Example (Four Adjoints)
(d), which is the geometric case; on , the map of the
symmetric , where conjugation does nothing
and ; and on , the map of the
Hermitian , where transposing swaps the two
off-diagonal entries and conjugating swaps them back,
while the diagonal is real and survives both.
Here is a non-example by minimal change: keep the
shape and move the conjugate. The matrix is
symmetric, , but , so
the clause fails. It fails visibly at and : , while . Over , self-adjointness
means Hermitian, never merely symmetric.
Two more self-adjoint operators come for free: the
combination of Example (Differentiation on a Polynomial Space),
and for any
, since by Theorem 11.6.2 (c)
and (d).
An operator is normal when it and its adjoint may
be applied in either order.
Definition
11.6.3 (Normal Operator)
An operator on a finite-dimensional inner product
space is normal if it commutes with its
adjoint:
In words: normality is one equation between two
operators on ,
with no vectors and no quantifiers in it. It does not
ask that and
be equal,
only that their order may be swapped, so it is strictly
weaker than self-adjointness.
Four examples, widening as they go. Every
self-adjoint operator is normal, since then both sides
are . So is
every invertible
with
— Section 7 calls these unitary — since then both sides
are ; the
quarter-turn of , with matrix in the standard basis, is
one, and it is not self-adjoint. On the operator with
matrix
satisfies by Theorem 11.6.2 (b),
which commutes with but is not equal to
it: normal and not self-adjoint. Widest of all, every
diagonal matrix is normal, since .
A non-example by minimal change: take the diagonal
matrix
and slide its non-zero entry off the diagonal. The
Jordan block on has and the two differ. The entries say what
went wrong. Writing for the map of , the entry of the first
matrix is and that of the second is
, so : the operator kills and its adjoint
stretches it to a unit vector.
Over ,
normality is the weakest hypothesis under which the
spectral theorem holds, and that is its reason for
existing. Chapter 12 will show that the diagonal example
is already the general one.
The facts available now, before any eigenvalue
theory, are the ones that follow straight from the
definition.
Proof.
(a) By conjugate
symmetry (Definition 11.1.1)
and self-adjointness, A complex number equal to its own conjugate is
real.
(b) Let
be orthonormal. By Theorem 11.2.1 the
-th coordinate of
is , so
the entry of
is , which is real by
(a).
(c) .
Part (a) is the first hint of the spectral theorem.
If
with ,
then , and since the left side is
real and is a positive
real, must
be real: a self-adjoint operator has no non-real
eigenvalues. Chapter 12 turns this observation into the
spectral theorems: a self-adjoint operator has an
orthonormal basis of eigenvectors, with real
eigenvalues; on a complex space the operators with an
orthonormal basis of eigenvectors are exactly the normal
ones, and on a real space exactly the self-adjoint ones.
None of that is proved here, and none of it is used
before then; but all of it is built from the adjoint and
the orthogonal geometry of this chapter.
Warning. “Self-adjoint”
cannot be read off an arbitrary basis. Being
self-adjoint is a property of together with the inner
product, and the Hermitian test applies only in an
orthonormal basis. The operator of
Example (The Transpose Rule Breaks)
is not self-adjoint, and its matrix in the standard
orthonormal basis, , is correctly
non-symmetric. But the self-adjoint operator ,
the orthogonal projection onto the first axis, has the
non-symmetric matrix in the basis of that example,
since
and . A non-symmetric matrix is evidence of
nothing until the basis is known to be orthonormal.
Exercises
A. Check your
understanding
Exercise
(A1)
- (a) State the
defining property of the adjoint of ,
including the domain and codomain of and all
quantifiers.
- (b) Which hypothesis
of Theorem 11.6.1 is
used to produce , and which theorem
supplies it?
- (c) True or false:
for every scalar .
Justify your answer.
- (d) State the
hypothesis needed for , and say what
goes wrong without it.
- (e) True or false:
. Justify your answer.
- (f) Give an example
of a normal operator that is not self-adjoint.
Solution.
(a) For , the
adjoint is the unique with for all
and
all (Definition 11.6.1).
(b)
Finite-dimensionality of , which is what Theorem 11.5.1
needs in order to represent the functional .
(c) False: (Theorem 11.6.2
(b)). Over the
two agree; over
take and
, so that
.
(d) Both bases
must be orthonormal (Theorem 11.6.3).
Without it the rule fails: Example (The Transpose Rule Breaks)
has but .
(e) False. The
correct statements are and (Theorem 11.6.5).
The two sides need not even live in the same space when
.
(f) on : commutes
with , but .
B. Practice
Exercise
(B1: Adjoints of matrix maps)
Let and , acting between the
complex spaces with the standard inner products.
- (a) Write down and as matrix
maps.
- (b) Compute the
matrices of and of , and
verify by direct
computation.
- (c) Verify that
is not
self-adjoint, and determine whether it is normal.
Solution.
(a)
and (Example (Four Adjoints)
(a)), with
(b) , so On the other side, and . The two matrices agree, as Theorem 11.6.2 (c)
predicts.
(c) , since the
entries are
and . But so
is normal (Definition 11.6.3)
and not self-adjoint.
Exercise
(B2: Adjoints on a polynomial space)
Let and , each with the coefficient inner
product of Example (Differentiation on a Polynomial Space),
so that and are orthonormal bases.
- (a) Find the adjoint
of , .
- (b) Find the adjoint
of , , where carries .
(Compare Theorem 11.5.1.)
- (c) Verify
directly.
Solution.
(a) , , , so in the
two orthonormal bases by Theorem 11.6.3.
Hence : delete
the constant term and divide by .
(b) is linear and . For we need for all , so comparing
coefficients of gives . In particular is
the Riesz vector of the evaluation functional at .
(c) is injective, since
forces , so by
Theorem 2.3.1. And
is
surjective: for every . So too, agreeing with Corollary 11.6.6
(a).
Exercise
(B3: Locating the kernel of the adjoint)
Let , and let with the standard inner products.
- (a) Find a basis of
and a basis
of .
- (b) Verify directly
that every vector of is orthogonal to every vector of , and that the
dimensions add to .
- (c) Find and , and check Theorem 11.6.5 (b)
in this case.
Solution.
(a) The two
columns
and are
independent, so they are a basis of and
. Since
,
the kernel of
is : the
equations and give .
(b) and . Since
these two vectors span , orthogonality extends to all of by linearity. The
dimensions are , as Theorem 11.6.5 (d)
requires.
(c) gives and , so and .
On the other side, by Corollary 11.6.6
(a), and , so . The two agree.
C. Going deeper
Exercise
(C1: The adjoint of integration)
Let and with the coefficient inner
products of Exercise (B2: Adjoints on a polynomial space),
and let
- (a) Find .
- (b) Let be
differentiation. Show that , although
.
- (c) Explain in one
sentence why (b) does not contradict Theorem 11.6.2
(e).
Solution.
(a) and , so
in the orthonormal bases of and of
, by Theorem 11.6.3.
Hence .
(b) , so and differ on :
while .
Yet for
every , by
differentiating the integral, or by multiplying the two
matrices: .
(c) Part (e) of
Theorem 11.6.2
applies to an invertible map, and is not invertible: it
is injective but not surjective, since . A one-sided inverse carries no information
about the adjoint.
Exercise
(C2: Skew-adjoint operators)
Let be a
finite-dimensional inner product space over and let satisfy
(such a
is called
skew-adjoint).
- (a) Prove that is purely
imaginary for every when , and that for
every when
.
- (b) Prove that every
skew-adjoint is
normal.
- (c) Suppose . Prove that is skew-adjoint if and
only if is
self-adjoint, and deduce that every can be
written
with
self-adjoint.
Solution.
(a) By conjugate
symmetry and , A complex number equal to minus its own
conjugate has zero real part, so is purely
imaginary. When the inner product is real, so the same
equation reads , forcing .
(b) and
, so the two agree.
(c) By Theorem 11.6.2 (b),
. If then , so
is self-adjoint; conversely, if then , so . For the
decomposition put Then .
Both are self-adjoint: by Theorem 11.6.2 (a),
(b) and (d), and
is times the
skew-adjoint operator ,
hence self-adjoint by the first part of (c). This is the
operator version of writing a complex number as .
Exercise
(C3: The adjoint in an arbitrary basis)
Let be a
finite-dimensional inner product space, let
be any ordered basis of , let be its Gram matrix,
, and let .
Hint: for (b), write the defining identity of
in the
coordinates of (a) and use that
for all
forces .
Solution.
(a) Write and
, so and .
Expanding in the first slot and then in the second,
(b) Put
and . By Theorem 4.1.1,
and . So (a) turns into Taking and reads off the entries, so . The Gram
matrix is invertible (Theorem 11.2.5
(c)), so , and starring both sides gives
,
using
(Theorem 11.2.5 (a))
and hence .
(c) If is orthonormal then
, so and the formula reads , which is Theorem 11.6.3. In
Example (The Transpose Rule Breaks)
the computation in the remark after it is exactly this
formula, with .