Chapter 17 §08 defined majorization and Chapter 19
§07 proved one half of the fact that makes it useful: a
doubly stochastic matrix can only even a vector out,
. The
other half was promised twice. Chapter 19 §07 ended by
saying that “this converse of the proposition is part of
the theorem of Hardy, Littlewood and Pólya, which
Chapter 21 takes up”, and Chapter 19 §09 listed among
its unfinished business “the theorem of Hardy,
Littlewood and Pólya, that exactly when
for a
doubly stochastic ”. This section pays
both. The proof builds out of one very simple
move, repeated: average two coordinates and leave the
rest alone.
Throughout, vectors are real, , and
and are Chapter 17
§08’s Definition 17.8.1.
Recall , the
decreasing rearrangement, and , the set of
doubly stochastic matrices of Definition 18.8.4:
non-negative entries, every row and every column adding
up to . Recall
also Proposition 19.7.6,
the half already proved: if and , then .
What is
still missing
Chapter 19 got the easy direction from Birkhoff’s
theorem in three lines. A doubly stochastic is an average of
permutation matrices, a permutation only rearranges
, and
majorization cannot see a rearrangement; so is an average of
vectors all majorized by , and the set of such
vectors is convex.
Read backwards, that argument gives nothing. It
starts from a matrix and produces a majorization. We now
want to start from the majorization , which is a
list of
inequalities about sorted partial sums together with one
equality of totals, and manufacture a matrix. Nothing in
Definition 17.8.1
mentions a matrix, so one has to be built.
One such matrix is in fact already available. Chapter
19 §07 observed that Theorem 17.8.5
realizes any as the diagonal of a Hermitian with 𝛌, while Lemma 19.7.5 writes
that diagonal as for a
doubly stochastic ; composing with the
permutation matrix that sorts gives with . What
that route does not give is any grip on , which arrives as the
squared moduli of the entries of a unitary matrix
supplied by an existence theorem. The construction below
builds by hand
instead, as a product of at most factors, each of
which averages a single pair of coordinates and fixes
the rest.
Here is the smallest case, done by hand, to see what
a construction might look like. Let and with both
decreasing, so and . Also , since subtracting from the
equal totals reverses the inequality. So , and
is a weighted
average of and
: if then , and otherwise
The equal totals then force . In
matrix form, and the matrix is doubly stochastic. So for
and sorted
vectors the converse holds, with a of a very special
shape.
This is the same computation as Lemma 17.8.3, where
the weights were and for a rotation and
the averaged numbers were two eigenvalues. There the
averaging was performed by conjugating a diagonal
matrix; here it is performed on the vector directly.
Both say: any number between two others is an
average of them, and that single fact is the engine
of this section.
Averaging
two coordinates
The
matrix above can be planted inside , at any pair of
positions. That gives the move we will repeat.
A T-transform mixes two coordinates and leaves
every other coordinate alone.
In words: is
the convex combination, with weights and , of doing nothing and
swapping two coordinates. Applied to a vector,
The two moved entries are averages of the old and , with the
same pair of weights used in both
slots, exchanged. In particular : a T-transform conserves the total, and
indeed conserves the total of the pair it touches.
The first thing to check is that these matrices
belong in the discussion at all.
Proof. Let with
, and
let be the
pair
interchanges. In the two positions and the entry of is , in the two
positions and
it is , in the remaining diagonal positions
both and carry a , so the entry is , and everywhere else it
is . Each entry is
therefore , , or , hence non-negative,
since and
. A
permutation matrix has exactly one in each row and each
column and zeros elsewhere (the remark after Definition 3.4.2),
so and
;
the same is true of , which is the
permutation matrix of the identity permutation. Hence
which says that every row and every column of
adds up to . By Definition 18.8.4, .
Solution.
(a) With , and , Eq. 21.1.1 gives
At ,
and ; at , and . So the
endpoints of the family are “do nothing” and
“swap”.
(b) No. It is
doubly stochastic, by the computation in Proposition 21.1.1
with replaced by
, but Definition 21.1.1
asks for the permutation matrix of a
transposition. Concretely, changes
all three coordinates of , while a T-transform
fixes at least of them.
(c) No: is outside , and the matrix
has the entry in
position , so
it is not even doubly stochastic. Applied to it gives , whose first
two entries are further apart than and : with the
“average” is not between the two numbers, and the move
spreads rather than evens.
Quick check. Let be the T-transform on
with , and let
.
Compute , and
verify directly from Definition 17.8.1.
Solution. and , so . Both
vectors are decreasing with total , and the running
totals are
against .
Since and
, (M1)
holds, and (M2) is the equal totals. So , as Proposition 19.7.6
already promised, since .
Warning. A product of
T-transforms is usually not a T-transform.
T-transforms are doubly stochastic, and so are their
products (this is checked inside the proof of the main
theorem below), but the product of two of them can move
every coordinate. Averaging coordinates and , then coordinates and , changes all three. The
theorem below produces a product, not a single
T-transform.
One
averaging step
Now the engine. Given , we want to push toward by one T-transform,
and we want a measure of progress that cannot stall. The
measure is the number of coordinates in which the two
vectors already agree.
Idea. Both vectors are sorted, so
compare them entry by entry. Somewhere is too big and
somewhere it is too small. Let be the
last place where is too big and the
first place after where it is too small;
between them the two vectors already agree. Averaging
coordinates and
moves down and up by the same
amount, and we move by exactly as much as the tighter of
the two deficits allows, so that one of the two
positions lands on exactly. Two things
then need checking, and they are not equally hard. The
partial sums are the easy one: the only ones that drop
are those between
and , and they
have slack at least to give away, while we give away no more
than that. The delicate one is that must come out
decreasing, since otherwise the lemma
cannot be applied to it again; that is what taking last buys, because it
makes the entries between and agree with ’s.
Proof. Write
and , with . Since both vectors are decreasing, Definition 17.8.1 says
for
and .
Step 1: the two indices. Some index
has :
otherwise for every , and since at least one
inequality is strict, so , contradicting . Let be the
largest index with .
Next, some index has . Suppose not. By the choice of , for every
; so for every , and subtracting
these from gives . Then because . For this contradicts , and
for it reads
, which is
false. So we may let be the
smallest index with and .
By the maximality of we have for , and by
the minimality of
we have
there. Hence
Step 2: the transform. Put Since
is decreasing and , , so and in particular . Also
, using . So satisfies , and Definition 21.1.1
gives a T-transform acting on with this . By Eq. 21.1.1, and for every other .
Step 3: (c), the count. By the
choice of ,
either , and then ; or , and
then . So agrees with in at least one of the
positions .
Neither position agreed before, since and . Every other
position is untouched. Hence the number of agreements
strictly increases.
Step 4: (a), the sorted order. Only
positions and
change, and lowers
and raises
. From and
, If , then . If , then by , and . If , then . Symmetrically, if then , and if then . Every remaining consecutive pair
consists of two untouched entries of the decreasing
. So is
decreasing.
Step 5: (b), the majorization. Write
. Since differs from
only at and , by and , In particular ,
which is (M2). For and for we have , which is (M1) there. For , the
identity
gives for
,
hence Now , using
(which is (M1), or when ) and the definition of . Therefore which is (M1) at . So . This
proves the lemma.
The choice of the two indices is the only delicate
part, and it is worth saying why the obvious alternative
fails, and where. Suppose were taken as the
smallest index with , keeping
as the smallest
index after with
. Step
5 would survive: the minimality of still gives for , so the
slack is
non-decreasing on instead of constant, and it is
therefore at least its value at . What breaks is Step 4. The entries strictly
between and need no longer agree
with ’s, and
lowering by
can push it
below , so
that comes
out unsorted and Lemma 21.1.2 cannot
be applied to it a second time. Take and , both
decreasing, with since , and both totals are . Choosing smallest gives and , so and , which is not decreasing; the rule
of the lemma gives instead, and ,
which is. Taking
last and first
after it makes the interval between them a stretch where
the two vectors already coincide, and that stretch is
what protects the order.
The
theorem
Theorem
21.1.3 (Hardy–Littlewood–Pólya Theorem)
Let . Then Moreover, if and are both decreasing,
may be taken to
be a product of at most T-transforms.
Idea. is Chapter
19’s Proposition 19.7.6 and
needs nothing new.
For , sort both
vectors first, since neither side of the equivalence
sees the order. Then count agreements. Lemma 21.1.2 raises
that count by at least one, keeps both hypotheses alive,
and therefore may be applied again; the count is at most
, so the process
stops, at turned
into . The bound
comes from
noticing that the count can never be exactly : two vectors with
equal totals that agree in all but one coordinate agree
in that one too.
Proof. If with , then
by Proposition 19.7.6.
Suppose .
Step 1: the decreasing case. Assume
first that and
are both
decreasing. For write for the number of indices with . We
claim:
Claim. If and are decreasing with
and
, then for some T-transforms with
if , and
otherwise.
Proof. First, : if and agreed in all indices
but one, say ,
then subtracting those equalities from the
equal totals (M2) would give too, so
. We induct on
.
If then
, and the
empty product, , works. Let , and assume the claim for every smaller
value. By Lemma 21.1.2 there is
a T-transform
with decreasing, and
. If
, then
and
.
Otherwise , since by the first paragraph applied to and ; the inductive
hypothesis gives with , so
. This proves the claim.
Since ,
the claim gives in every case. This proves the
“moreover” clause.
Step 2: products stay doubly
stochastic. If , then has non-negative
entries, and , ; so by Definition 18.8.4. By
induction, any finite product of doubly stochastic
matrices is doubly stochastic. With Proposition 21.1.1,
the matrix of Step 1 lies in .
Step 3: the general case. Let be arbitrary.
Majorization sees only rearrangements (the remark after
Definition 17.8.1), so
, and Step 1 gives with
. Choose permutations with
and ; these exist because
is
a rearrangement of and of . Each
is doubly
stochastic, having exactly one in each row and each
column and zeros elsewhere (the remark after Definition 3.4.2),
so by Step 2 This proves the theorem.
Two remarks on what the theorem does and does not
say. It converts a family of inequalities and
one equality into a single algebraic identity , and an
identity is much easier to feed into another argument,
as the next section does, one row of at a time. And the
in the
“moreover” clause is sharp; Exercise (C3: The count cannot be
improved) exhibits a pair needing that many.
Example
(Four coordinates, two transforms)
Let and . Verify , run the construction of Theorem 21.1.3, and
write out the resulting .
Solution. Both vectors are
decreasing with total , and the running
totals are for
against
for . So (M1) and
(M2) hold and .
First step. Here ,
so the only index with is , giving ; the smallest index above it with is . Then and
is the T-transform on with : Now agrees with in positions and , where before it agreed
only in position .
Second step. , so and , with and .
The T-transform on gives Two transforms, and .
The matrix. Multiplying row by row,
Every row adds up to , and so does every
column: the first is , the third is
, and
the second and fourth are visibly . Finally Note that is not a T-transform:
it moves three of the four coordinates.
Warning. The matrix is far from unique,
and “doubly stochastic” cannot be relaxed to
“row-stochastic”. For and , both
are doubly stochastic with . And if only
the rows are required to add up to
, the conclusion
fails: with and the row-stochastic , , whose
total is ,
so . The column condition is what enforces the
equal totals.
Majorization as a polytope
Birkhoff’s theorem turns the doubly stochastic matrix
of Theorem 21.1.3 into
an average of permutations, and the statement becomes
geometric.
Corollary
21.1.4 (Majorization Is Membership in a
Permutation Polytope)
Let . Then
Proof. By Theorem 21.1.3, with . By Theorem 19.7.2, , so by Theorem 18.1.3, with and . Hence
, a convex combination of the
vectors , which lies
in their convex hull by Theorem 18.1.3.
By
Theorem 18.1.3, with a list
of non-negative weights adding up to . Put . Its entries are non-negative,
and , , so and . By Proposition 19.7.6,
.
The set is
the permutation polytope of : the convex hull of
the
rearrangements of . It lies in the affine
subspace where the coordinate sum equals , so its
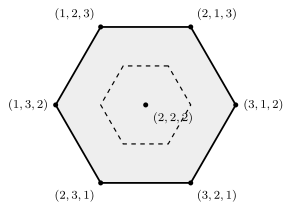
dimension is at most . For and distinct entries it is a hexagon.
The solid hexagon is the permutation polytope of
,
drawn inside the plane ; the dashed one, at half the
size, is the polytope of .
By Corollary 21.1.4,
says
that lies in the
solid hexagon, and says that the
dashed hexagon sits inside the solid one. The
majorization order is containment of permutation
polytopes. The center , the flat vector,
lies in every one of them, which is Example (A chain, the two extremes, and size one)
(b) again.
Exercises
A. Check your
understanding
Exercise
(A1)
- (a) Define a
T-transform, and say which coordinates of a vector it
can change.
- (b) State the
Hardy–Littlewood–Pólya theorem in full.
- (c) True or false:
if with
row-stochastic
(non-negative entries, every row adding up to ), then . Justify your
answer.
- (d) True or false:
if , the
doubly stochastic with is unique.
Justify your answer.
- (e) In Lemma 21.1.2, why is
chosen as the
largest index with rather than
the smallest?
- (f) Why can the
number of coordinates in which two decreasing vectors
agree
never be exactly ?
Solution.
(a) For and
, it
is with the permutation matrix
of the transposition of and (Definition 21.1.1).
It changes only the coordinates and , replacing each by an
average of the two old values.
(b) For , if and only
if for
some doubly stochastic ; and when and are both decreasing,
may be taken to
be a product of at most T-transforms (Theorem 21.1.3).
(c) False. With
and
, has total
while has total , so (M2) fails. Row
sums alone control nothing but the individual entries;
the column sums are what preserve the total.
(d) False. For
and
, both
and the
matrix of the
warning after Example (Four coordinates, two transforms)
send to .
(e) Because it
makes the entries strictly between and agree with ’s, which is what Step
4 needs in order to keep decreasing. The
majorization would survive the other choice: with smallest, the slack
is
non-decreasing on rather than constant, hence still at
least
throughout, and Step 5 goes through. The sorted order is
what fails, and with it the possibility of applying the
lemma again. For and , taking smallest gives , , and ,
which is not decreasing, while the rule of the lemma
gives and
, which is.
(f) Suppose they
agree in all indices but . Subtracting the
equalities
from the
equal totals of (M2) leaves , so in
fact they agree everywhere.
B. Practice
Exercise
(B1: Run the construction)
Let and . Verify , produce T-transforms with by the
recipe of Lemma 21.1.2, and
write out . Hence check that is doubly
stochastic.
Solution. Both vectors are
decreasing with total , and the running
totals are
against . So
(M1) and (M2) hold and .
First step. , so and . Then
and , and acts on :
Second step. , so , ,
and . Then
The matrix. has rows ,
, , and has rows ,
, .
Multiplying, Each row adds up to , and the columns add up
to , and . So , and
.
Exercise
(B2: Determine which are majorizations)
For each pair, determine whether . Where it
holds, exhibit a doubly stochastic with ; where it
fails, name the clause of Definition 17.8.1 and
the value of at
which it fails. Justify your answer.
- (a) , .
- (b) , .
- (c) , .
- (d) , .
Solution.
(a) Both
decreasing, totals ; running totals against . So . Here is the flat vector,
and
works: every entry of is .
(b) Totals , but at the sorted first
entries are , so (M1) fails at and .
(c) Sorted,
and ; this is (b) again, so , with
(M1) failing at .
(d) Totals , so (M2) fails
and . (Both running totals do satisfy (M1), so
.)
Exercise
(B3: Into the polytope)
Let and . Using Corollary 21.1.4,
write explicitly
as a convex combination of rearrangements of , in two different
ways.
Solution. The six rearrangements of
are the vectors
with entries in some order. Averaging the three cyclic
shifts, Alternatively, average a vector with its
reversal: Both are convex combinations, with weights
and . This
is the non-uniqueness of the warning after Example (Four coordinates, two transforms),
seen on the polytope: is the center of the
hexagon, lying strictly inside it rather than on an
edge, and such a point has many representations. (The
hexagon itself has empty interior in , since it lies in
the plane ; “inside” here means inside the hexagon,
within that plane.)
C. Going deeper
Exercise
(C1: Row-stochastic is not enough, twice over)
Let be row-stochastic:
every entry is non-negative and every row adds up to
.
- (a) Give such an
and a with .
- (b) Prove that if
for
every , then is doubly
stochastic.
Hint for (b): test the hypothesis on the standard
basis vectors.
Solution.
(a) Take and . Then , whose total
is , while has total . So (M2)
fails.
(b) Apply the
hypothesis with . The vector is the -th column of , by Definition 0.9.9. From
,
clause (M2) gives So every column of adds up to . The entries are
non-negative and the rows add up to by hypothesis, so is doubly stochastic
by Definition 18.8.4.
Exercise
(C2: Transitivity, a second time)
- (a) Prove that if
then .
- (b) Hence deduce
that
and
imply ,
and compare this route with the proof of Proposition 17.8.1
(b).
Solution.
(a) The entries
of are , sums
of products of non-negative numbers, hence non-negative.
Since and
, we get
, so every row of adds up to . Since and , we get
, so every column does too. By
Definition 18.8.4, .
(b) By Theorem 21.1.3 there
are with and . Then , and by (a). By Theorem 21.1.3 again,
.
Proposition 17.8.1 (b)
proved the same thing in one line, by chaining the
inequalities between running totals. That proof is
shorter and uses nothing. The route here is longer, but
it explains transitivity rather than verifying it: a
majorization is an averaging, and averaging twice is
averaging.
Exercise
(C3: The count cannot be improved)
Let ,
and in . For , write .
- (a) Show that .
- (b) Let be a T-transform.
Prove that for
every .
- (c) Deduce that no
product of fewer than T-transforms sends to .
Solution.
(a) Both vectors
are decreasing with total . Every running total of
is , and the -th running total of
is . So (M1) and (M2)
hold.
(b) Let act on with parameter
. By Eq. 21.1.1, for , so
If both , the right side is
and there is nothing to prove. If neither is, then , so
and again . In the
remaining case exactly one of them, say , lies in ,
and then , a
set with one more element. In all cases the bound
holds.
(c) Suppose .
Put
and . Then and . By
(b), the size of the support grows by at most at each step, so Together with Theorem 21.1.3, which
gives such a product with , exactly transforms are needed for this
pair.